AI Model Serving Frameworks for Production APIs
Production AI APIs need three distinct layers: inference, serving, and orchestration.
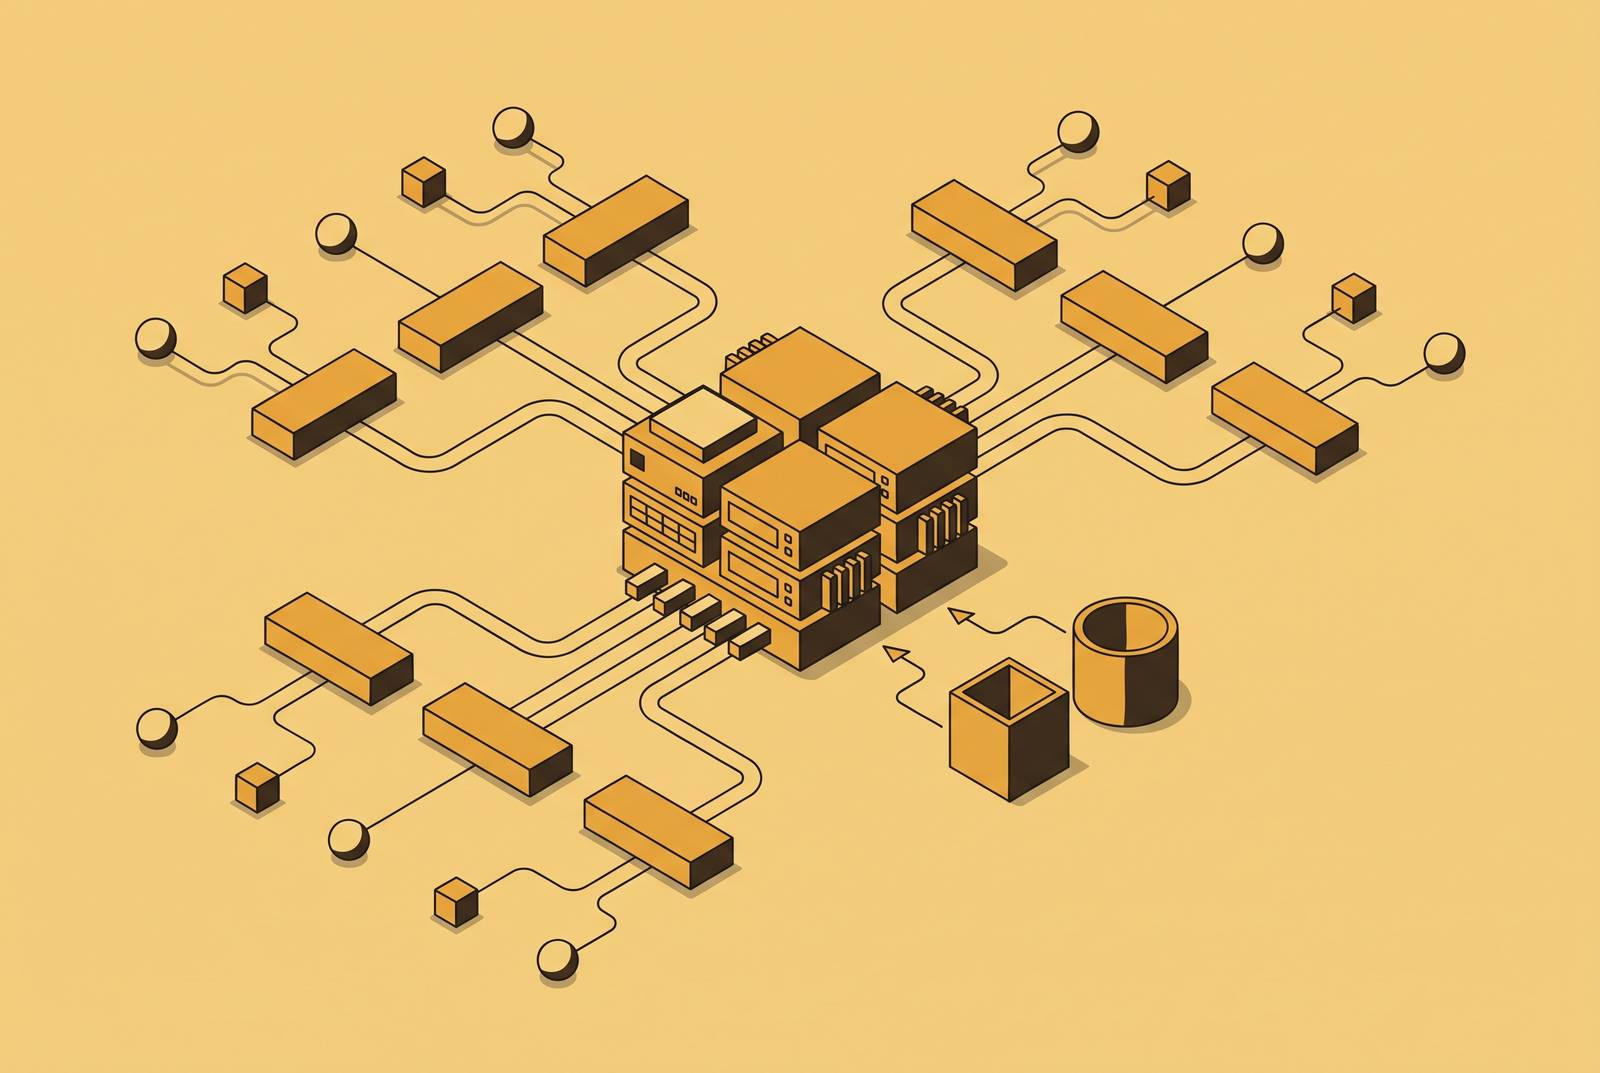
A production AI API is not a model plus a framework. It is a three-layer system: an inference engine that executes computations, a serving layer that mediates requests, and an orchestration layer that keeps the whole thing scaled and healthy. Teams that treat model serving as a single tool decision end up with infrastructure that works in a demo and degrades under real load. The gap is not model quality or hardware cost. It is architectural clarity.
Why the inference engine alone cannot make a production API
A team picks a framework, gets a model running behind a simple serving endpoint, and watches it handle a few dozen requests without issue. Then traffic climbs, VRAM fills, requests queue, and latency spirals. The instinct is to blame the framework or the hardware. The actual problem is that the team optimized one layer of a system while leaving the other two unbuilt.
RunPod's architecture guide frames the situation directly: getting capable models and affordable hardware is no longer the bottleneck. Serving them at scale is. Each of the three layers has its own failure modes, and a team that knows its inference engine cold but has not thought through orchestration will still hit ceilings under concurrent load. An inference engine executes forward passes correctly regardless of traffic volume. What it cannot do is route requests intelligently, enforce API contracts, scale replicas, or recover from failed pods. Those responsibilities live elsewhere, and pretending they belong to the engine is how fragile deployments are born.
What model size and modality commit you to before you pick any framework
The model being deployed sets hard constraints on every layer below it, so the framework decision cannot precede the model decision. A dense model that fits comfortably on a single GPU makes modest demands on the inference engine and the serving layer alike. A large mixture-of-experts model spread across nodes requires distributed inference pathways, careful memory management, and orchestration that understands topology.
RunPod's guide names DeepSeek R1 as a recurring benchmark reference precisely because its MoE routing and long chain-of-thought outputs stress-test distributed inference in ways a small dense model never would. The spread across model sizes is what makes "which framework should I use" unanswerable without knowing the model first. A framework that is the obvious choice for a smaller model may be the wrong one for a model an order of magnitude larger, even on the same hardware. Multimodal serving adds a further dimension: text, image, video, and audio in a single endpoint make demands that not every inference engine handles equally well. The model is the first architectural fact. Every other decision follows from it.
The inference engine layer: what it actually does and the three engines that handle most production workloads
The inference engine's job is narrower than most teams assume. It loads weights onto accelerators, executes forward passes, and manages the KV cache. Understanding that scope is what makes hardware and engine tradeoffs legible, because it clarifies what an engine cannot do. An engine does not deploy itself, does not autoscale, and does not manage multi-tenancy. It is a computational component, not a platform.
Concurrency at this layer is a memory problem before it is a compute problem. Each concurrent request holds KV cache, so VRAM sets the ceiling on simultaneous users, not raw FLOPS. A card with abundant compute but constrained memory will stall under modest concurrency, and no amount of optimization at the serving or orchestration layer changes that physical fact. This is why inference engine selection must account for how memory pressure will behave under the expected request mix.
RunPod's guide identifies three open-source engines handling the bulk of production workloads as of early 2026: vLLM, SGLang, and TensorRT-LLM. vLLM is the default starting point for most teams, with an active contributor base spanning AMD, NVIDIA, IBM, Red Hat, Google, and academic labs including UC Berkeley. That breadth brings hardware optionality, though frequent releases also mean version-compatibility issues are common. SGLang excels in multi-turn and structured generation, achieving higher throughput in certain benchmarks and fitting agentic and programming-heavy workloads well. TensorRT-LLM is the NVIDIA-pinned path, the right choice when maximum throughput on NVIDIA hardware is the overriding goal.
A universal API contract has emerged around the OpenAI format. vLLM and SGLang expose the endpoints natively, and TensorRT-LLM natively exposes chat and completions endpoints while embeddings requires a separate trtllm-serve subcommand. Existing OpenAI SDKs work as drop-in clients against any of them. That practical compatibility is the reason the ecosystem converged on these three engines. Above one GPU, architecture matters more than the card: replicating a small model behind a load balancer beats sharding it across GPUs, because tensor parallelism adds communication overhead that hurts latency at low batch sizes.
The serving layer: routing, batching, and the API contract between the engine and the outside world
The serving layer is the part most teams do not explicitly design, and its absence is usually what turns a working single-user demo into an API that degrades under load. Its responsibilities are distinct from the engine's: request routing, batching, API contract enforcement, streaming response management, rate limiting, and the interface between the outside world and the inference engine. None of these is execution. All of them determine how well the engine's capacity is used.
RunPod's guide names LiteLLM, Envoy AI Gateway, and Triton as serving-layer components whose primary job is mediation rather than execution. Triton deserves particular attention here, because it occupies a position that framework comparisons often misread. Triton is heavily oriented toward NVIDIA GPUs, with CPU and non-NVIDIA paths as secondary considerations, and NVIDIA AI Enterprise adds official support and a certified deployment path on top of the free open-source version. Its serving-layer strengths lie in ensembling and multi-framework batching, capabilities that operate above the inference engine rather than competing with it.
The OpenAI-compatible API has become a de facto serving contract. Because vLLM and SGLang expose it natively, teams can swap inference engines without rewriting client code. The serving layer's contract is now largely standardized even when the engine underneath is not. Dynamic batching is this layer's primary throughput lever: grouping requests that arrive independently into a single forward pass raises GPU utilization without changing the engine. That is the kind of win the serving layer exists to deliver, and it is invisible to anyone who assumes the engine handles it.
The orchestration layer: scaling, health, and the Kubernetes-native options that manage the layers below
Orchestration is where reliability and elastic scale actually get delivered. The inference engine and serving layer handle each request correctly. The orchestration layer ensures there are always enough instances to handle the next thousand. Its responsibilities include autoscaling down to zero, health checking, rolling deployments, resource allocation across GPUs, multi-replica management, and traffic routing between model versions.
RunPod's guide names Kubernetes with KEDA, llm-d, NVIDIA Dynamo, and KServe as the orchestration-layer examples. KServe carries weight among enterprise Kubernetes teams in part because the CNCF accepted it as an incubating project, a legitimacy signal that matters when platform decisions require organizational buy-in. It offers event-driven autoscaling in Serverless mode and metric-based autoscaling in Standard mode, along with multi-framework support, A/B testing, and canary rollouts. The tradeoff is real: KServe requires Kubernetes expertise and adds overhead for smaller teams without DevOps resources.
Ray Serve is the Python-native alternative, built on Ray and scaling across clusters. It supports batch and real-time inference, model composition, and multi-model pipeline serving, and it is the natural fit for teams already running Ray for distributed compute. The Ray Serve plus vLLM pairing is standard for teams that need multi-replica orchestration and autoscaling without moving to a fully managed platform. KEDA is the mechanism that ties GPU queue depth to replica count. Without it, autoscaling responds to CPU and memory signals that do not reflect GPU saturation. Above one GPU, replication behind a load balancer outperforms tensor parallelism for small models, and the orchestration layer is where that topology gets expressed.
How the three layers fit together: the reference stack a team can actually build from
The three layers are independent choices that must compose cleanly, and a small number of reference combinations cover the vast majority of production use cases. For most LLM serving teams, the baseline is vLLM at the inference layer, LiteLLM or Envoy AI Gateway at the serving layer, and KServe or Ray Serve at the orchestration layer. For NVIDIA-pinned, heterogeneous model fleets, TensorRT-LLM pairs with Triton spanning inference and serving, with KServe or Kubernetes plus KEDA above it. Teams living in the Hugging Face ecosystem can take TGI at the inference layer with Hugging Face Inference Endpoints managing serving and orchestration. Python-native distributed compute teams can compose vLLM with Ray Serve without Kubernetes expertise at all.
The OpenAI-compatible API contract is what makes these combinations interchangeable. The serving layer is the stable interface point: teams can swap inference engines beneath it or orchestration above it without rewriting client code. The practical decision rule crystallizes here as well. Replicate behind a load balancer for small models. Move to tensor or pipeline parallelism only when the model does not fit on a single GPU. These reference stacks are not a ranking. They are decision rules tied to team context, and a team that understands the three layers can sketch its own stack from them.
When to stop running the stack yourself: what managed platforms actually abstract away
Managed inference platforms are not a simpler version of the self-hosted stack. They are a different organizational tradeoff that makes sense when GPU and Kubernetes expertise is the binding constraint, not engineering cost. What a managed platform actually abstracts is the operational surface of all three layers: GPU provisioning, kernel optimization, multi-cloud failover, and uptime SLAs. The team interacts with an API and a deployment config, not with CUDA drivers or Kubernetes CRDs.
Baseten is the most prominent example. It serves LLMs, embeddings, transcription, speech synthesis, image and video generation, and compound AI systems through Chains. Its Inference Stack pairs optimized GPU runtimes with a capacity manager that abstracts multiple cloud providers behind a single deployment. Active-active redundancy and automated multi-cloud failover target 99.99% uptime. Deployment options include fully managed Baseten Cloud with optional single-tenant clusters, self-hosted, or hybrid with spillover, and pricing is usage-based on per-minute compute or per-token with custom enterprise terms. A significant funding round in 2026 signals strong enterprise adoption.
TrueFoundry offers Kubernetes-native deployment plus an AI gateway in one platform, available as SaaS, VPC, or on-premises and air-gapped. Its tiered pricing runs from free through Pro at $499 per month, Pro Plus, and custom Enterprise. Hugging Face Inference Endpoints provides one-click deployment from the model hub, a strong fit for text-focused teams that need access to a large pre-trained repository without building serving infrastructure, though pricing runs higher than some alternatives. The honest tradeoff cuts both ways: managed platforms remove operational burden but reduce the ability to tune the inference or serving layer for specific workload characteristics. Teams chasing maximum throughput on owned hardware will outperform managed platforms. Teams that need to ship fast without GPU expertise will not.
Observability across the three layers: what to instrument and why most teams instrument too little
A three-layer stack that is not instrumented at each layer is not production-ready. It is a stack that fails silently, because GPU saturation, KV cache pressure, and routing errors each require different signals to detect. The inference layer needs KV cache utilization, time-to-first-token, tokens per second per request, and batch queue depth. These reflect GPU memory pressure and batching efficiency that CPU and memory metrics miss entirely. The serving layer needs request latency distribution across p50, p95, and p99, error rates by endpoint, streaming connection duration, and rate-limit hit rate. The orchestration layer needs replica count against queue depth, pod restart rate, GPU node availability, and rolling deployment success rate.
The most common gap is that teams instrument the API endpoint with latency and error rate but not the inference engine with KV cache and batch queue metrics. They learn about GPU saturation from user complaints rather than from dashboards. That is a failure of layer separation, not of tooling. Observability is a layer-specific discipline, not a single monitoring product, and a team that treats it as one will keep discovering its blind spots from the wrong side.
The framework decision: mapping team constraints to the right combination of layers
The right serving framework is not the one with the best benchmarks. It is the combination of layer choices that fits the team's actual constraints: model size, hardware access, Kubernetes expertise, and time-to-production. Four decision axes make the choice derivable from first principles rather than guesswork.
Model and hardware come first. A dense small model on a single GPU points to vLLM with replication. A large MoE model across nodes points to vLLM or TensorRT-LLM with pipeline parallelism and orchestration via KServe or NVIDIA Dynamo. A heterogeneous model fleet points to Triton as the serving layer. Team expertise is the second axis. A strong Kubernetes team reaches for KServe at orchestration. A Python-native distributed compute team reaches for Ray Serve. A team with no GPU or Kubernetes expertise should consider a managed platform, with Baseten, TrueFoundry, or Hugging Face Inference Endpoints selected by model source and deployment environment.
Workload type is the third axis. Multi-turn and agentic workloads favor SGLang as the inference engine. Structured generation favors SGLang as well. Maximum raw throughput on NVIDIA favors TensorRT-LLM. Broadest hardware optionality favors vLLM. Operational posture is the fourth. A team needing 99.99% uptime without building it should choose a managed platform with active-active redundancy. A team needing to tune for specific workload characteristics should self-host with full observability. The OpenAI-compatible API contract is the invariant across all of these choices. Whatever combination of layers a team picks, preserving that interface at the serving layer keeps client code stable as the infrastructure evolves. That is what the three-layer frame makes tractable. Without it, teams compare tools that operate at different layers as if they were alternatives, and the framework decision becomes a lottery.