Automating Release Announcements for Open Source Projects
Machine-generated release notes need evidence and discoverability, not just publication speed.
Automating release announcements for open source projects is no longer just about turning commits into readable notes. It also means making those announcements a source that the AI systems developers ask for advice can draw on. The full approach pairs a release pipeline that works reliably with content backed by evidence, a plan for where to share it, and citation tracking. Publishing the notes finishes the mechanical work, leaving the discovery work to be done.
Why release announcements are now a two-layer problem
Manual releases leave maintainers collecting changes, checking version numbers, assembling artifacts, and writing explanations when the code is already ready. Automation removes much of that repetitive work. A tagged commit can become formatted, published release notes in under a minute, replacing hours of manual effort. For a project that releases often, that is a substantial operational improvement. But speed answers only the question of how the announcement gets published.
Developers increasingly shift from a search results page to asking ChatGPT, Perplexity, Gemini, or Claude when discovering tools. An announcement may be available on GitHub yet absent from the answers those developers receive. The finish line has moved beyond the publication event.
These are two distinct layers of work. The mechanical layer needs commit messages that follow the same rules, release triggers, packaging tools, and a workflow for publishing. The discovery layer needs useful evidence, retrievable sources, and a way to measure whether engines actually reference them. Neither substitutes for the other. A flawless pipeline does not supply a benchmark, while a well-written announcement cannot repair an incomplete release artifact.
What the mechanical pipeline actually does, step by step
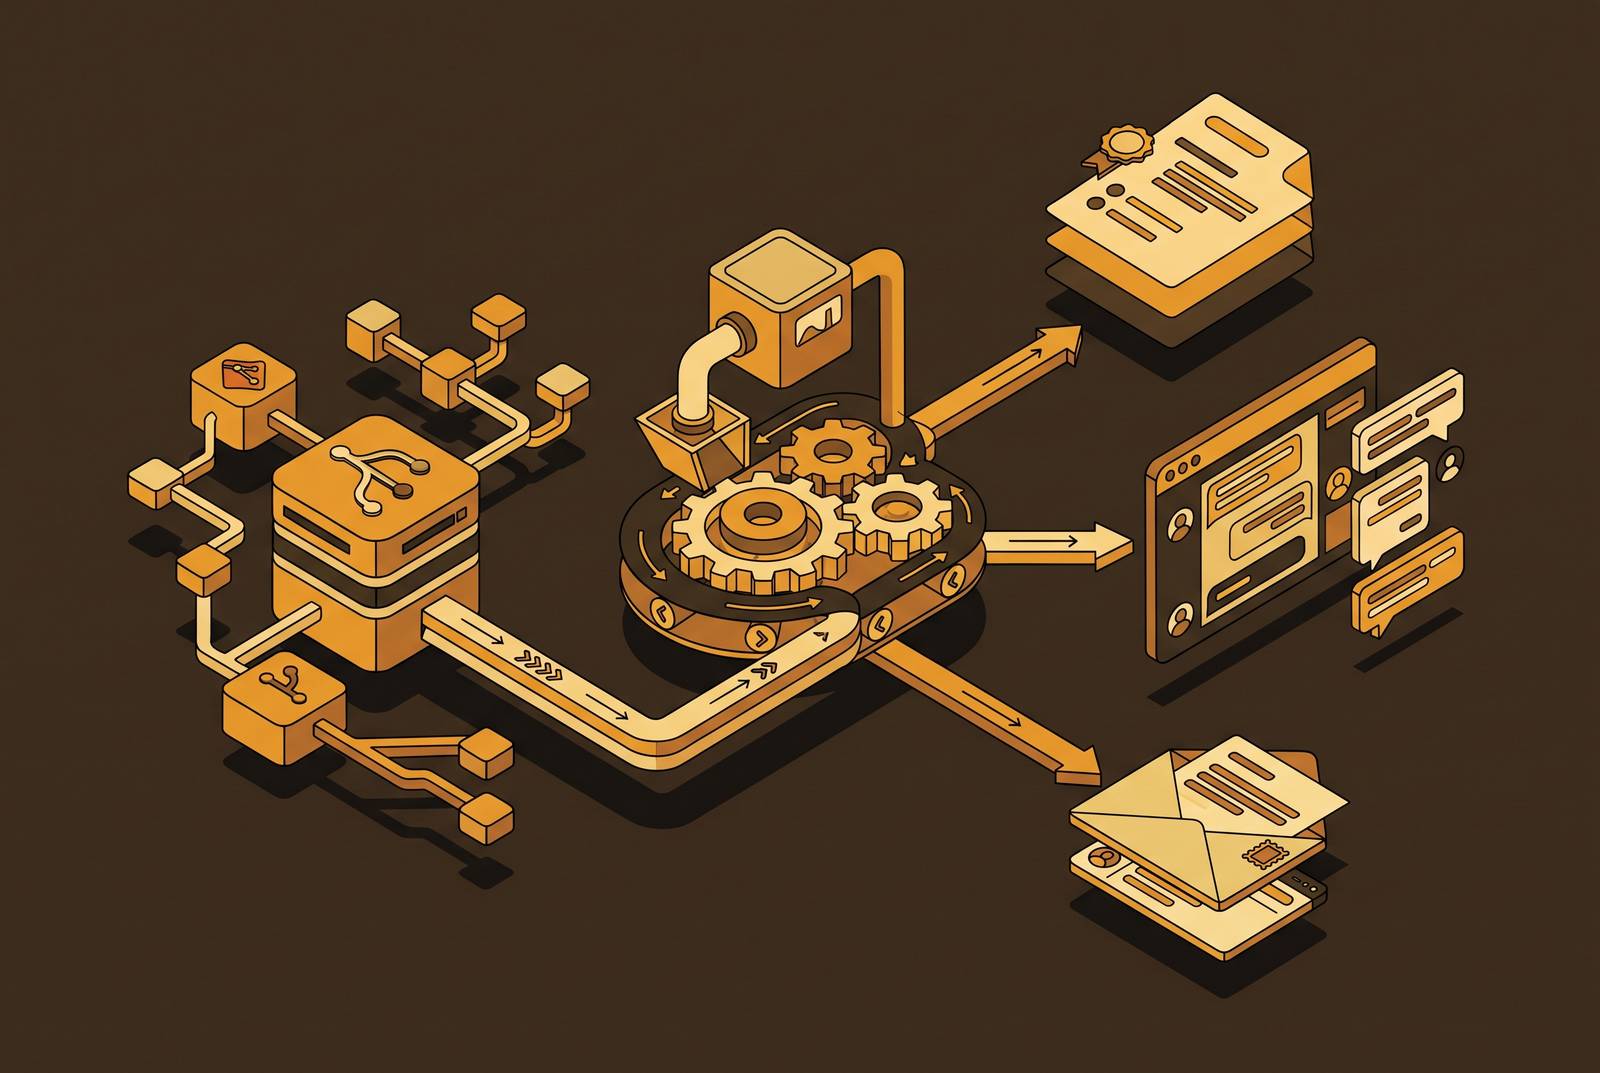
A reliable mechanical pipeline covers six sequential steps. It first detects a release through a tag push, manual trigger, or merge to main, then builds and tests the code. Next, it generates or updates the changelog and creates the release artifacts. It then publishes to package registries and creates a GitHub Release containing the notes and artifacts. Each step needs to be wired before AI-assisted drafting can help make the notes read better.
The commit convention is the load-bearing input. Generators can only interpret the messages they receive, and Conventional Commits supplies the format most depend on. Drafting tools can make rough input read smoothly, making it easy to miss the need for clear records at the start. Fluency can improve presentation without improving the reliability of the release history being presented.
The established tools serve different parts of that workflow. semantic-release provides fully automated version management and package publishing, while release-it automates versioning and package publishing. Release Drafter drafts the next release notes as pull requests merge into master. Commitizen creates committing rules, automatically bumps versions, and generates changelogs. For application packaging, goreleaser delivers Go binaries, while cargo-dist handles shippable Rust applications.
The output format also shapes what comes next. HTML supports richer embeds and links, while JSON enables structured data and schema markup. Plain text is portable but limits formatting useful to Generative Engine Optimization. The mechanical pipeline should leave room for the content and distribution layer and each destination's format needs, with evidence still required in richer formats.
Why a machine-generated changelog does not earn AI citations
What does a polished changelog actually prove? Usually, it records what changed without showing what those changes let a developer do. That is valuable release documentation, but it does not by itself supply a reason for an AI answer engine to cite the project. Generative Engine Optimization, also called Answer Engine Optimization, concerns making content easy for those systems to find, understand, and reference. Its signals and format requirements differ from those of conventional search optimization.
The distinction begins with the evidence an answer needs. AI systems can reproduce generic information learned from many sources without attributing it to a particular release announcement. Original benchmark data, named comparisons, and quantified release-specific claims offer something different. They give an answer a verifiable reference. A list of commit messages, even rewritten into polished prose, supplies no such evidence unless the underlying inputs already contain it.
Authority follows a different pattern as well. Brand mentions correlate more strongly with AI citation probability than backlinks do, while the relationship between traditional link authority and AI visibility is weak. That correlation leaves open whether more mentions will produce citations. A project's release pages can perform well in search without becoming a dependable source for generated answers.
The strongest objection is therefore understandable but incomplete. If release notes already rank on Google, surely they are visible? They are visible in that setting, but ranking on a results page and being cited in an answer are different jobs. AI-referred evaluators may bypass the results page entirely. Standard release notes also do not reliably provide self-contained answer blocks that can be extracted without losing the context needed to understand a claim.
How to build a release announcement that AI systems can cite
A release announcement should add evidence through quantified, verifiable claims drawn from the release itself, such as measured performance ratios, before-and-after benchmark comparisons, or concrete counts of resolved issues. These release-specific details give technical evaluators a firmer basis for assessment than a general claim that a release is faster or more capable. Where a benchmark supports the announcement, its methodology and context belong with the result.
Each important paragraph should answer a likely question in full. What improved, compared with what, and under which conditions? A reader or retrieval system should be able to lift that paragraph without turning a qualified finding into a blanket promise. This is the purpose of a self-contained answer block. It preserves the link between the claim and the evidence instead of leaving essential qualifications elsewhere on the page.
A longer companion post can provide the context that a short GitHub release note cannot comfortably hold, including migration guidance and use-case examples. Length alone is not the goal. The evidence on page length and AI citations is inconclusive, so padding a page to reach a target has no sound basis here. The reason to expand is that a developer needs a fuller answer. If the short note already supplies that answer, extra words do not improve it.
Freshness gives release cadence a second use. Recently updated content has a citation advantage, making each release an opportunity to refresh an anchor document. The anchor can keep the background that explains the changes while staying up to date with the current release. That connects the latest announcement to a useful reference. It also gives the drafting process a clearer body of material to work from.
Once the inputs have been checked and gathered, drafting should follow a clear anti-fabrication constraint. Claims must stay within those inputs, even when stronger wording would sound more persuasive. A self-critique pass should then check for unsupported claims, missing context, and inconsistencies. Before publication, a person then checks that the draft is accurate and takes editorial responsibility for it. These stages distinguish automated writing from unattended publication.
The review gate also has a legal dimension. The EU AI Act transparency rules applicable from 2 August 2026 include an exemption for AI-generated or AI-manipulated text published to inform the public on matters of public interest. The exemption requires substantive human review or editorial control and a natural or legal person holding editorial responsibility for publication. The standard's relevance depends on the publication and applicable obligation.
Where to publish a release announcement so AI systems find it
The major engines draw from different source pools, so publication on GitHub Releases alone does not reliably reach the sources they favor. Content quality and distribution are separate constraints. The announcement needs an authoritative home, but it also needs corroboration beyond that home. Otherwise, an owned page is being asked to do all the discovery work.
The available source profiles show why one channel is insufficient. ChatGPT favors Wikipedia and Reddit, with the largest share of its citations across queries going to Wikipedia and Reddit close behind. Claude favors citations from premium editorial brands and from its own brand site. LinkedIn accounts for a large share of Perplexity's social citations. Citation of an individual release post on a favored platform remains uncertain.
Those findings do not provide a matching source profile for Gemini, and Perplexity's social citation pattern is not a description of every source it uses. Filling those gaps with assumptions would weaken the distribution plan. Measurement must establish what happens for the project's own category and announcements.
The recommended architecture starts with a canonical long-form post on the project's own domain, the ground site. Distribution then extends to Reddit, Hacker News, LinkedIn, and relevant developer communities as corroborating sources. The layer5io/blowhorn-site project offers a concrete example of this queue-based pattern. It demonstrates coordinated multi-channel distribution by posting a release or project milestone to GitHub, Slack, Hacker News, Reddit, LinkedIn, X, and Bluesky from a single queue, with maintainers amplifying from their own profiles as themselves.
Technical additions should not displace that work. FAQ schema and an llms.txt file lack documented meaningful coverage lifts in the evidence supplied here, so neither deserves to be treated as a high-leverage shortcut. A richer publishing format makes these additions possible without proving they will improve citation rates. Most AI citations come from sources outside the project's own domain. That makes corroboration a structural part of the approach.
Measuring whether your release announcements are actually being cited
The pipeline is incomplete until its discovery layer is instrumented. A published artifact proves that the mechanical process ran, but it says nothing about whether a developer encountered the release through an AI answer. The same release cadence can run a structured prompt battery against each engine. These queries should reflect questions developers plausibly ask when evaluating tools in the project's category. Repeating them provides a record.
Each engine needs its own record of results. Only a small fraction of sites are cited by both ChatGPT and Perplexity, so success on one cannot stand in for visibility on the other. Results for Gemini and Claude should be tracked in the same way. Otherwise, an aggregate view can hide an engine where the project rarely appears.
Google Search Console has free, built-in Search Generative AI performance reports that are a starting point for tracking the Google AI Mode signal. Google's official announcement describes separate views of impressions in generative AI features, including AI Overviews and AI Mode, with a Pages dimension that shows which URLs appeared. That is useful page-level visibility data. It should not be treated as a substitute for observing citations in the other engines. ChatGPT, Claude, and Perplexity need the structured prompt battery to establish what their answers include.
For each query on each engine, the log should distinguish a mention from a linked citation. It should also record the source cited and the adjacent projects appearing in the same answer. Those are different outcomes. A project name may appear without its announcement receiving attribution, while a third-party source may receive the linked citation. Competitive citation share shows how the project's citation count compares with those of other projects.
The measurement cadence should align with releases and run at least monthly, because citation share fluctuates as models retrain. Checking again over time helps show whether a drop lasts or is just short-term noise. A decline on one engine can then guide a targeted response, including refreshing the content types it indexes, adjusting the channel mix, or adding structured evidence. That feedback closes the second layer of automation. The next release improves not only the software and its notes, but the evidence available to developers deciding whether to use it.