Content Velocity vs Content Quality Tradeoffs at Scale
Measure AI content against separate ranking and citation quality floors, not just output volume.
The problem facing content teams in 2026 is not a choice between speed and quality. Companies need to rank across competitive keywords and build visibility inside AI platforms, and that takes far more output than any small team can produce by hand, so the pressure to scale is structural, built into the math of modern search and discovery, not a failure of discipline or ambition.
AI-assisted production removes that ceiling. The constraint shifts from whether a team can produce enough content to whether what gets produced is worth publishing. At the same time, the cost of a quality miss has gone up, not down. The question that matters is what kind of pipeline lets a team move both fast and carefully, and that question is architectural.
What "quality" means when content runs at scale
Quality at scale is not a feeling an editor has when reading a draft, and it is not an average taken across a content library. It functions as a floor, a minimum bar that every published piece has to clear, and that floor has two components that do not substitute for one another: ranking quality, which governs how content performs in traditional search, and citation quality, which governs whether AI answer engines surface and credit a brand.
Ranking quality depends on depth, sourcing, and structure, not word count. Before any team increases output, it has to answer a concrete question: what does "good enough to publish" mean for this brand, specified in terms of topics covered, sources cited, and editorial standards applied, not left as a vague aspiration.
Citation quality operates under a separate and stricter logic. Getting cited requires content built around quotable conclusions, structured FAQ sections, and clear entity markup, not keyword density, so a language model can attribute a claim to a source rather than paraphrasing it anonymously. A piece can hold the top spot on Google and still never appear inside ChatGPT: optimizing for one channel does nothing to guarantee performance in the other.
One practical way to operationalize this without applying identical investment to every piece is tiering: pillar content built to rank and convert, regular content built for engagement and topical coverage, and experimental content built to test new angles or formats. Each tier carries its own quality floor, and the system holds together only when that floor is stated explicitly for each tier rather than assumed to be uniform across the whole library. The place this discipline usually breaks down is measurement. Most marketing teams have no systematic way to know whether AI-assisted content is actually producing results or just producing output. Letterstory and platforms like it measure whether ChatGPT, Claude, Gemini, and Perplexity actually name and cite a brand, which turns citation quality from an assumption into something a team can check before publishing the next piece. Without that kind of measurement, "quality" becomes whatever happened to ship, and the floor disappears without anyone deciding to remove it.
How pure-velocity strategies fail
Pure-velocity strategies rarely collapse immediately. The more common pattern is a slow compounding of damage: early traffic gains mask quality decay for long enough that the decline becomes structural and expensive to reverse by the time it becomes visible.
The pattern tends to unfold in stages. In the first stage, volume appears to work. In the second stage, quality signals start to diverge from the volume metrics. Thin or repetitive pieces begin to drag down the stronger content on the same domain, and that is the domain-level penalty in practice, not just in theory.
The most insidious part of this trajectory is the treadmill it creates: a library that gains visibility through high-volume publishing but can't hold an audience because the content lacks substance ends up needing constant new output just to replace the engagement it keeps losing. Structural causes, more often than individual carelessness, produce this pattern. If a team spends most of its content-pipeline time in approval loops, with only a small fraction left for actual creation, it can still post an impressive publication count while throughput quietly fails. The velocity number can look strong on a dashboard even as the quality and impact numbers deteriorate behind it. None of this reflects carelessness so much as a predictable response to incentives that reward visible output over verified outcomes.
The corrective is to reduce velocity temporarily, tighten the quality process, and rebuild output at a pace the pipeline can actually sustain. That corrective only works, though, if the pipeline itself is built to support it, which is the question the next section takes up directly.
Why pipeline architecture is the deciding variable
The teams that sustain both speed and per-piece quality are not distinguished by better AI tools or larger editorial staffs. They are distinguished by having designed human judgment into the pipeline as a gate, placed at a specific point in the process, rather than treating review as an afterthought applied to whatever already got produced.
The distinction that matters is architectural. In a bolted-on review setup, AI drafts everything, and a human just reads through the resulting pile at the end, right before it gets published. That human becomes a bottleneck by design: review gets rushed or skipped outright when the workload spikes, and quality turns inconsistent because it depends entirely on how much time happens to be available on a given day. A built-in review setup looks different. The pipeline has discrete stages, and human review sits as a named gate between two of them, not as a catch-all at the end. The reviewer sees a shorter, already-filtered piece and can make a real editorial judgment grounded in that reduced workload.
Multi-agent systems are what make built-in review workable at scale. Specialized agents can handle discrete stages, research, structural scaffolding, drafting, optimization, and pre-publication scoring, so that by the time a human reviewer sees a piece, the mechanical errors and the obvious quality failures have already been caught upstream. This repositions the human editor from a first-draft reader into a strategic and voice reviewer, which is a fundamentally different job with a fundamentally different workload. The review gate sits in the middle of that chain by design, not tacked on at the end as a formality.
The stage most teams skip is pre-publication automated scoring, and skipping it is the reason the human gate stops scaling. Before a human ever reads a piece, automated checks against brand voice, preferred terminology, compliance standards, and markers of generic AI-voice writing should filter out the work that never should have reached a human reviewer. That filter is what converts the human gate from a bottleneck into a focused decision point, since the person reviewing is now looking at a short list of pieces that have already cleared a mechanical bar, not a long list of everything an agent happened to produce that day. Quality assurance doesn't end at the moment a piece gets published, either. Facts go stale, terminology shifts, and AI search visibility changes over time, so content that was accurate and on-brand at launch needs periodic re-checking, or the quality floor erodes gradually even inside a pipeline that was well designed to begin with.
What a well-architected pipeline looks like end to end
A functional content pipeline at scale runs through five named stages, and each one has a specific, identifiable failure mode if a team skips it or collapses it into a neighboring stage.
The first stage is intake and brief. Topic selection, audience targeting, the quality floor for this piece's specific tier, and source requirements all get established before any drafting starts. This is where the quality floor gets operationalized. Skipping this stage leads writers or agents to optimize for word count and keyword presence instead of the actual question the piece needs to answer.
The second stage is research and competitive analysis. A research agent maps what already exists on the topic, identifies the gaps in that existing coverage, and gathers source material, a task distinct from drafting that should never be collapsed into it. If a team skips this stage, the resulting draft recycles material that is already indexed elsewhere, adds nothing new, and earns no citations from anyone, human or algorithmic.
The third stage is drafting with voice calibration. For content meant to be citable by AI answer engines, the draft at this stage should already include quotable conclusions, inline sourcing, and structured FAQ or answer blocks, formatting choices that make it easy for a language model to attribute a claim to its source.
The fourth stage, pre-publication automated scoring, is the one most pipelines skip. Before a human reads the draft, it gets checked automatically against brand voice, preferred terminology, compliance requirements, and markers of generic AI output. This is the filter that makes the human gate efficient instead of overwhelming, since the pieces that clear it are the only ones that reach a human reviewer; everything else gets returned to drafting for revision.
The fifth stage is the human review gate itself. A human editor reviews a piece that has already been filtered, checking for strategic direction, voice, factual accuracy, and final approval. This is non-negotiable, not an optional polish pass applied when time allows, and the human reviewing it has to retain the ability to say no and send a piece back. Automation that removes the capacity to reject a draft isn't a pipeline at that point; it's a firehose with a human standing in front of it.
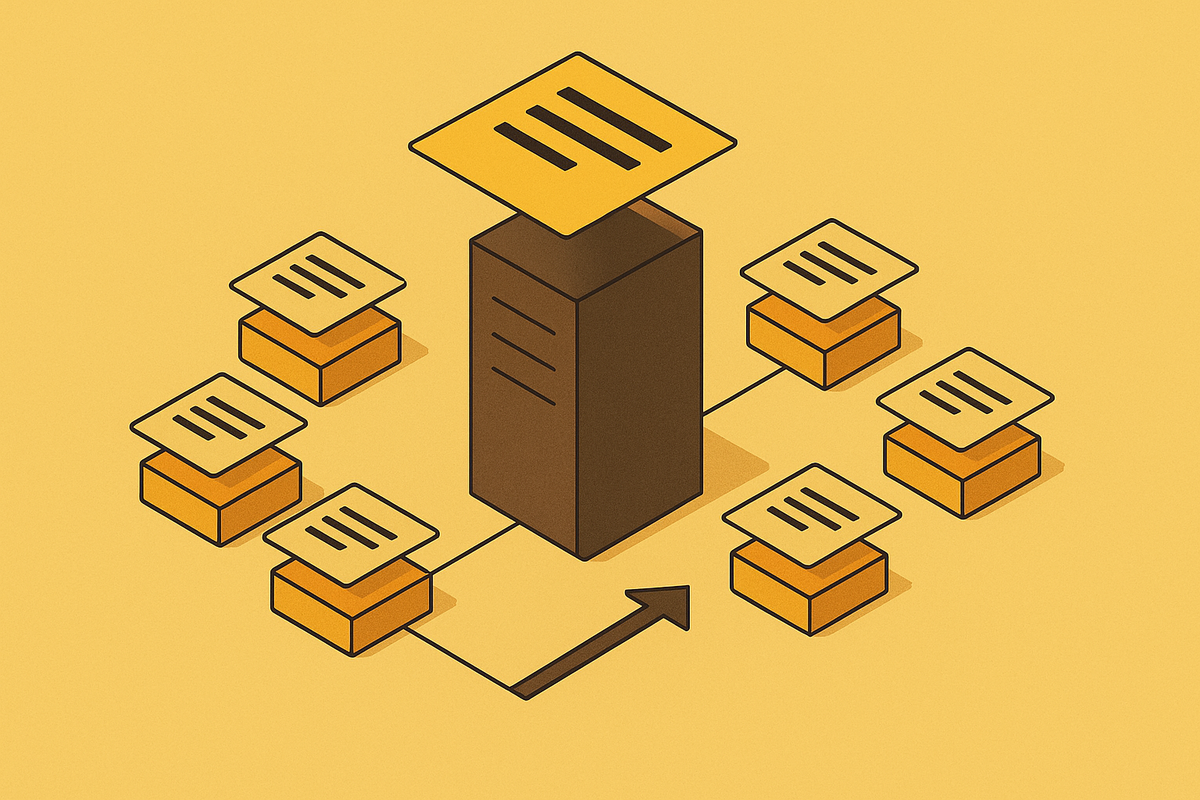
The sixth stage is post-publish monitoring. Scheduled re-checks catch stale facts, terminology drift, and shifts in how a piece performs inside AI search, so publication becomes the start of a piece's working life, not the finish line. Repurposing adds another lever to this structure: a single pillar piece can generate several derivative pieces across different formats, multiplying distribution without multiplying the full production cycle each derivative would otherwise require. That is how a well-architected pipeline achieves real velocity without quietly degrading the investment made in each individual piece.
Services and platforms that can run this kind of pipeline
A buyer evaluating pipeline vendors can reduce the decision to a single architectural question: does the human review gate sit inside the system as a named, mandatory step, or is it left as the buyer's own responsibility to bolt on afterward?
Letterstory is built explicitly around the architecture described above: AI handles drafting, and human review functions as a designed-in gate rather than an optional add-on, under the operating principle that every AI-generated suggestion should be reviewable and reversible before it ships. The platform is built for teams that are done treating AI visibility as an afterthought bolted onto old SEO content, a framing that lines up directly with the architectural argument made throughout this piece.
Other paths exist for teams with different needs. Some vendor platforms integrate directly with CMS environments, supporting draft-to-scheduled-publication workflows and covering content velocity strategy for startups and for generative-engine optimization as part of their guidance. Other organizations build their own internal pipelines by chaining discrete AI stages themselves, such as a sequence of Discovery, Performance Analysis, Transcription, Voice-Aware Scriptwriting, a Human Review Gate, and a Publishing Layer, which stands as one working example of built-in review. That path gives a team full architectural control and the ability to compose capabilities through an API, but it demands real engineering investment to build and maintain the quality gates, and it suits organizations that already have the technical capacity and specific stack requirements no vendor pipeline will fully match.
Measuring whether the pipeline is working, for Google and for AI answer engines
A pipeline can be architected correctly and still drift toward volume over quality if nobody instruments it, because the metrics teams track by habit, posts published, words produced, raw traffic, reward throughput, hide per-piece impact and AI citation performance.
There are two distinct measurement jobs here, and they don't collapse into one dashboard. AI answer-engine visibility needs its own dedicated measurement layer, tracking whether ChatGPT, Claude, Gemini, and Perplexity actually name and cite the brand in their answers, since standard web analytics have no built-in mechanism for detecting a citation or a brand mention inside a synthesized AI response.
Citations and named mentions are not interchangeable, and conflating them produces a misleading picture. Visibility also varies sharply by platform: citation volumes for the same brand can differ enormously between engines like Grok and Claude, so a single measurement taken from one engine does not generalize to the others, and any useful measurement effort has to cover multiple engines at once.
Any one of these calls for reducing velocity temporarily and tightening the quality process, consistent with the corrective already established for pure-velocity failure.
The measurement layer earns its real value by feeding back into the intake stage. Stale facts, drifting terminology, and shifts in AI visibility identified after publication should trigger updates to existing content, not just new production aimed at a different topic. That feedback loop is what closes the pipeline into a cycle instead of leaving it as a one-directional push from brief to publish. Letterstory's measurement layer tracks named mentions and citations specifically across ChatGPT, Claude, Gemini, and Perplexity, which is the kind of instrumentation that turns AI visibility into a managed outcome rather than something a team simply hopes is happening in the background.